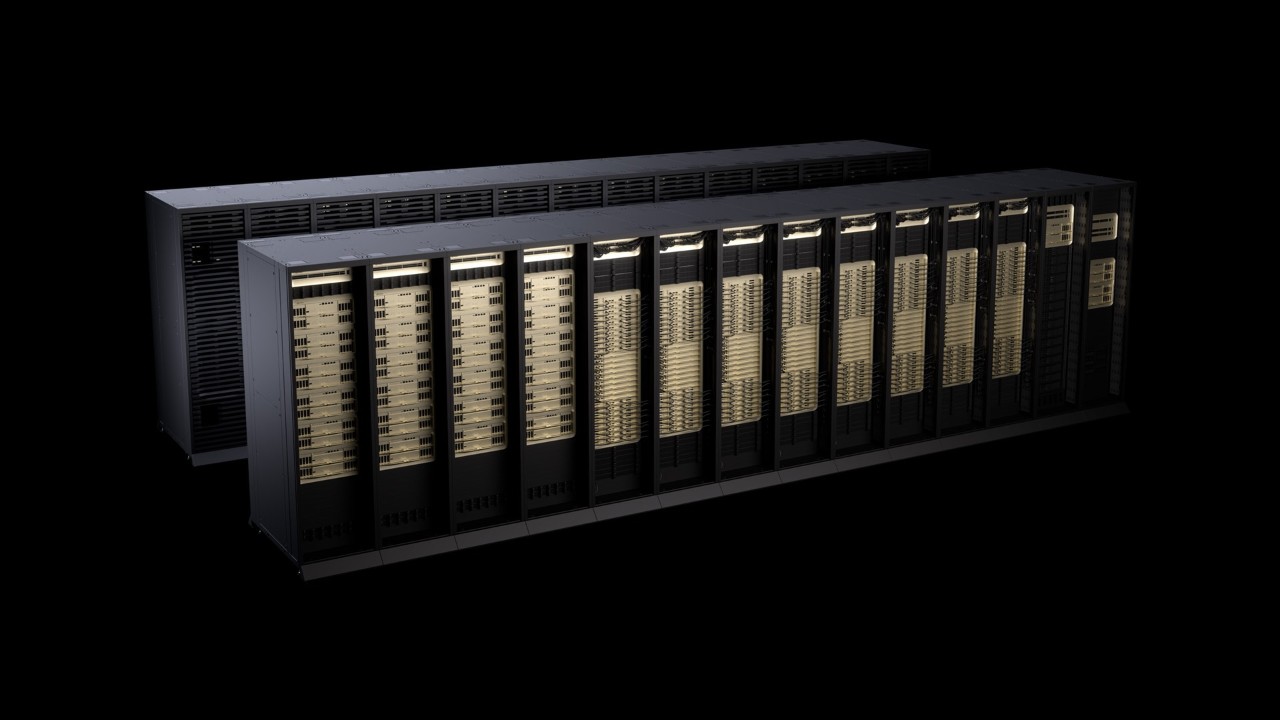
NVIDIA DGX Vera Rubin NVL72
$3,000,000.00
NVIDIA DGX Vera Rubin NVL72 is a graphics card from NVIDIA. Product Information Brand: NVIDIA Model / identifier: DGX Vera Rubin NVL72 Product type: AI Infrastructure / Accelerator Availability: In stock Model: DGX Vera Rubin NVL72 Type: AI Infrastructure / Accelerator Applications Buyers should assess compatibility.
Review the model information, technical details, compatibility, included configuration and documentation before requesting a destination-specific B2B quotation.
Explore Related
Related products, categories and research.
NVIDIA DGX Vera Rubin NVL72
NVIDIA DGX Vera Rubin NVL72 is a turnkey, liquid-cooled rack-scale AI infrastructure system built around 72 NVIDIA Rubin GPUs and 36 NVIDIA Vera CPUs. It is designed for large-scale AI training, post-training, reasoning and high-throughput inference rather than use as a conventional PCIe graphics card.
The platform combines Rubin GPUs, Vera CPUs, sixth-generation NVIDIA NVLink, ConnectX-9 networking, BlueField-4 DPUs and the NVIDIA DGX software stack in a single enterprise AI platform. NVIDIA positions DGX Vera Rubin NVL72 for organizations building gigascale AI factories where compute, networking, power, cooling and operations must be engineered together.
Commercial availability: price, current allocation, deployment lead time, support scope, networking options, logistics and destination-specific delivery should be confirmed in a written quotation before purchase.
NVIDIA DGX Vera Rubin NVL72 for gigascale AI training and inference
NVIDIA DGX Vera Rubin NVL72 is designed for enterprises, sovereign AI programs, AI laboratories, cloud and neocloud operators, hyperscale data centers and research organizations that need a tightly integrated platform for demanding AI workloads.
Instead of treating individual accelerators, CPUs and network adapters as separate procurement decisions, the system is engineered as a rack-scale compute domain. NVIDIA combines 72 Rubin GPUs with 36 Vera CPUs and a sixth-generation NVLink fabric so the rack can support very large models and high-throughput workloads with substantially more tightly coupled compute than conventional multi-server designs.
The platform is particularly relevant to agentic AI and reasoning workloads, where long contexts, tool use, repeated inference steps and large mixture-of-experts models can create heavy demands on GPU memory, GPU-to-GPU communication and system-wide data movement. It is also designed for pretraining, post-training, reinforcement-learning workflows, multimodal AI and large-scale inference.
For a buyer, the important point is that NVIDIA DGX Vera Rubin NVL72 is not simply “72 GPUs in a rack.” The purchase affects the entire facility: cooling-water design, power distribution, scale-out network topology, storage, rack placement, monitoring, workload orchestration, support and commissioning all become part of the project.
NVIDIA DGX Vera Rubin NVL72 specifications
The following table is based on NVIDIA’s current DGX Vera Rubin NVL72 product specifications. Values marked by NVIDIA as preliminary should be reconfirmed before final purchase approval.
| Specification | NVIDIA DGX Vera Rubin NVL72 | Buyer relevance |
|---|---|---|
| System class | Turnkey rack-scale AI infrastructure / DGX system | Requires data-center-level planning rather than workstation or add-in-card installation. |
| GPU configuration | 72× NVIDIA Rubin GPUs | Designed for very large training and inference workloads. |
| CPU configuration | 36× NVIDIA Vera CPUs | Supports host, orchestration and agentic workloads tightly coupled to the GPU complex. |
| Total GPU memory | 20.7 TB HBM4 | Important for large-model residency, KV cache, multimodal models and high-concurrency inference. |
| GPU memory bandwidth | NVIDIA detailed specification currently states up to 1,580 TB/s; its quick-spec block currently lists 1,400 TB/s | Because NVIDIA’s own current page contains both figures, buyers should confirm the latest datasheet value for the final configuration. |
| NVFP4 inference | 3,600 PFLOPS | Manufacturer theoretical specification for low-precision AI inference. |
| NVFP4 training | 2,520 PFLOPS (dense specification) | Relevant to Rubin-generation training and post-training workloads. |
| FP8 / FP6 training | 1,260 PFLOPS (dense specification) | Supports training workloads that use higher numerical precision. |
| NVLink | Sixth-generation NVIDIA NVLink | Creates the high-bandwidth scale-up domain across the rack. |
| NVLink switch system | 9× L1 NVIDIA NVLink switches | Central to rack-scale GPU-to-GPU communication. |
| Compute networking | More than 144× OSFP single-port ConnectX-9 VPI, 800 Gb/s InfiniBand and Ethernet | Scale-out network design and optics/cabling must be planned before installation. |
| Infrastructure networking | More than 18× dual-port BlueField-4 VPI, 400 Gb/s InfiniBand and Ethernet | Supports DPU-based infrastructure services and high-speed I/O. |
| Management | Host BMC with RJ45 management interface | Relevant to data-center management, monitoring and service workflows. |
| Software | NVIDIA Mission Control, NVIDIA AI Enterprise, NVIDIA DGX OS | Provides the operational software stack around the hardware platform. |
| Enterprise support | Three years of enterprise business-standard support for hardware and software, per NVIDIA’s current product specification | Confirm support entitlement, region and service process in the quotation. |
Performance values are manufacturer specifications, not guarantees for every application. Real workload performance varies with model, precision, batch size, software stack, network design, storage, thermal conditions and optimization.
NVIDIA DGX Vera Rubin NVL72 and the MLPerf Inference v6.1 debut
On September 16, 2026, NVIDIA published results from its first preview MLPerf Inference v6.1 submission using Vera Rubin NVL72. NVIDIA reported up to 3.7× higher throughput than GB300 NVL72 on Qwen3-VL across specified offline, server and interactive scenarios, and up to 2.5× higher throughput on DeepSeek-R1 in the comparisons it highlighted.
MLCommons’ independent MLPerf Inference v6.1 release confirms the arrival of new and soon-to-be-released hardware in a peer-reviewed benchmark round and describes the benchmark suite as architecture-neutral and reproducible. This provides useful third-party context for procurement teams evaluating vendor performance submissions.
The commercial importance of these results is not just peak throughput. At rack scale, higher useful throughput can affect token economics, user concurrency, required rack count, power utilization and the amount of infrastructure needed to serve a target workload. Buyers should therefore compare both benchmark results and facility-level total cost of ownership.
For organizations deciding between an available Blackwell Ultra platform and a Rubin deployment, benchmark maturity and delivery timing matter alongside peak performance. A system that can be deployed immediately may create value sooner, while a new greenfield AI factory with a later deployment date may justify designing directly around Rubin-generation networking, cooling and operations.
Why NVIDIA DGX Vera Rubin NVL72 is an AI factory system, not a graphics card
The NVIDIA Rubin GPU is the accelerated-compute engine for training and inference. NVIDIA positions Rubin around agentic AI, reasoning, multimodal AI and large-scale model workloads.
NVIDIA Vera uses 88 custom Olympus cores per CPU. In DGX Vera Rubin NVL72, 36 Vera CPUs provide the CPU layer for demanding AI-factory workloads.
Sixth-generation NVLink creates the scale-up fabric that allows the rack’s GPUs to communicate at bandwidth far beyond ordinary server networking.
ConnectX-9 provides the high-speed scale-out networking required when multiple racks or storage systems must communicate at AI-factory scale.
BlueField-4 DPUs add infrastructure acceleration and help separate infrastructure services from application compute.
NVIDIA Mission Control is designed to help configure, operate and manage DGX infrastructure, including interaction with cooling and power events.
Direct liquid cooling and facility design
NVIDIA describes Vera Rubin NVL72 as a liquid-cooled rack-scale platform. NVIDIA’s technical documentation states that the platform uses warm-water, single-phase direct liquid cooling and builds on the same 45°C supply-temperature approach used for Blackwell rack-scale systems.
This has immediate purchasing implications. A customer should not order NVIDIA DGX Vera Rubin NVL72 and only afterward ask whether the facility can cool it. CDU capacity, supply/return-water design, redundancy, leak detection, heat rejection, rack placement and facilities monitoring should be validated during project design.
Power and electrical planning
Rack-scale accelerated infrastructure can place very different demands on a facility from conventional enterprise servers. Buyers should confirm the exact electrical specification and required redundancy from the latest NVIDIA reference architecture and the supplied configuration. Power distribution, branch circuits, protection, facility headroom and backup strategy should be engineered around the deployed rack rather than estimated from individual GPU specifications.
Scale-out network planning
The rack provides extremely high internal GPU communication through NVLink, but multi-rack AI factories still require a scale-out fabric. NVIDIA positions Quantum-X800 InfiniBand and Spectrum-X Ethernet for Rubin-scale infrastructure. The correct design depends on cluster size, topology, workload characteristics, storage architecture, redundancy and the customer’s existing network.
NVIDIA DGX Vera Rubin NVL72 vs GB300 NVL72
The most useful current comparison is with NVIDIA GB300 NVL72, a Blackwell Ultra rack-scale platform that also combines 72 GPUs and 36 CPUs. The two systems occupy a similar class of AI-factory infrastructure, but Vera Rubin moves to the next GPU, CPU, interconnect and networking generation.
| Area | DGX Vera Rubin NVL72 | GB300 NVL72 | Buying implication |
|---|---|---|---|
| GPU generation | 72 Rubin GPUs | 72 Blackwell Ultra GPUs | Rubin is the newer architecture; GB300 has an established current-generation deployment path. |
| CPU generation | 36 Vera CPUs | 36 Grace CPUs | Vera is designed for the Rubin-era platform and agentic workloads. |
| GPU memory | 20.7 TB HBM4 | 20 TB GPU memory | Both are very large rack-scale memory domains; architecture and bandwidth matter alongside capacity. |
| NVLink generation | 6th generation | 5th generation | Rubin advances the scale-up interconnect architecture. |
| Scale-out NIC generation | ConnectX-9 | ConnectX-8 | Networking design changes with the platform generation. |
| Infrastructure DPU | BlueField-4 | BlueField-3 in NVIDIA’s current GB300 reference architecture | Infrastructure offload and data-path architecture evolve with Rubin. |
| Availability decision | Confirm current allocation and deployment schedule | NVIDIA lists GB300 NVL72 as available now | Time-to-deployment may outweigh future-generation performance for some projects. |
For buyers who do not need a full NVL72 rack, a smaller NVIDIA DGX B300 deployment can be a different class of purchase. The correct comparison should be based on model size, concurrency, training/inference mix, cluster scale, facilities readiness and budget—not simply on which product name is newest.
Planning a Rubin or Blackwell Ultra deployment?
Send your target model/workload, required deployment date, quantity, destination country and existing data-center constraints. AI Robot Supplier can prepare a B2B sourcing quotation and coordinate configuration questions before order approval.
What must be ready before NVIDIA DGX Vera Rubin NVL72 arrives?
- Facility cooling: validate direct-liquid-cooling architecture, coolant distribution, redundancy, monitoring, water quality and heat rejection.
- Electrical capacity: confirm the latest rack power requirements, distribution topology, redundancy and facility headroom for the exact supplied configuration.
- Rack and floor planning: confirm access route, loading, placement, service clearances and local data-center constraints before shipment.
- Scale-out networking: define InfiniBand or Ethernet architecture, switch layer, optics, cables, port count, topology and redundancy.
- Storage: ensure training data, checkpoints, RAG datasets and inference pipelines can feed the GPUs without creating an I/O bottleneck.
- Management network: reserve management connectivity, BMC access and integration with existing monitoring and operations systems.
- Software: validate DGX OS, NVIDIA AI Enterprise, Mission Control, framework versions, containers and internal application dependencies.
- Security: define network segmentation, administrative access, secrets management, workload isolation and confidential-computing requirements where applicable.
- Support process: document support entitlement, escalation path, spare/service workflow and responsible teams before production cutover.
- Commissioning: establish acceptance testing for compute, network, cooling, monitoring and target workloads before declaring the system production-ready.
Organizations without existing liquid-cooled AI-factory infrastructure may need significantly more lead time for site preparation than for hardware procurement itself. For that reason, NVIDIA DGX Vera Rubin NVL72 should usually be treated as an infrastructure project rather than a conventional server purchase.
NVIDIA DGX Vera Rubin NVL72 price, configuration and buying checklist
NVIDIA does not present a simple universal public retail price for a complete DGX Vera Rubin NVL72 deployment on the current product page. Final commercial pricing can depend on configuration, support, deployment scope, networking, installation services, logistics, destination and market allocation.
For a useful quotation, provide as much of the following information as possible:
- Quantity of DGX Vera Rubin NVL72 systems or target GPU count.
- Destination country, city and installation facility.
- Desired delivery or production date.
- Primary workload: pretraining, fine-tuning, post-training, inference, multimodal, agentic AI, HPC or mixed use.
- Expected model sizes, context lengths and concurrency targets where known.
- Existing network: InfiniBand, Spectrum-X Ethernet or greenfield design.
- Cooling infrastructure and available facility-water parameters.
- Required support level and commissioning assistance.
- Any required freight, cargo insurance, import documentation or onsite coordination.
- Exact NVIDIA system/configuration and revision.
- Quantity and current availability/lead time.
- Included networking, cables, optics, accessories and software entitlement.
- Support period and service route.
- Shipping terms, insurance, destination charges and customs responsibility.
- Installation, commissioning or onsite services, if included.
- Payment milestones and inspection/acceptance procedure.
Is NVIDIA DGX Vera Rubin NVL72 right for every AI buyer?
No. The platform is aimed at organizations with workloads and infrastructure requirements large enough to justify rack-scale accelerated compute. A company training smaller models, running moderate inference volumes or lacking liquid-cooled data-center infrastructure may be better served by a smaller DGX, HGX or individual GPU-server deployment.
The strongest reason to consider NVIDIA DGX Vera Rubin NVL72 is not simply that Rubin is newer than Blackwell. It is that the workload benefits from the combined GPU memory, NVLink scale-up domain, next-generation networking and integrated operations of a purpose-built AI-factory system.
Applications for NVIDIA DGX Vera Rubin NVL72
Large language, multimodal and foundation-model training where tightly coupled GPU communication and very large memory capacity are important.
Long-context, tool-using and multi-step AI systems that can generate significantly more inference work per user request.
Cloud, enterprise and service-provider deployments where throughput, concurrency and token economics can justify rack-scale infrastructure.
Fine-tuning, reinforcement learning and optimization workflows that combine large training and inference phases.
Vision-language, video generation and other workloads that place heavy demands on memory, compute and data movement.
Large-scale research programs that need accelerated compute, high-bandwidth interconnects and enterprise operations.
NVIDIA DGX Vera Rubin NVL72 documentation and benchmark sources
NVIDIA DGX Vera Rubin NVL72 FAQ
What is NVIDIA DGX Vera Rubin NVL72?
NVIDIA DGX Vera Rubin NVL72 is a turnkey rack-scale AI infrastructure system combining 72 NVIDIA Rubin GPUs, 36 NVIDIA Vera CPUs, sixth-generation NVLink, ConnectX-9 networking, BlueField-4 DPUs and NVIDIA’s DGX software stack. It is designed for large-scale training and inference, not as a desktop graphics card.
How much GPU memory does NVIDIA DGX Vera Rubin NVL72 have?
NVIDIA currently lists 20.7 TB of total HBM4 GPU memory for the system. NVIDIA labels current specifications as preliminary and subject to change, so confirm the latest datasheet at the time of purchase.
How many GPUs and CPUs are in DGX Vera Rubin NVL72?
The current NVIDIA specification lists 72 Rubin GPUs and 36 Vera CPUs.
What networking does DGX Vera Rubin NVL72 use?
NVIDIA’s current DGX specification lists more than 144 single-port ConnectX-9 VPI OSFP interfaces at 800 Gb/s and more than 18 dual-port BlueField-4 VPI interfaces at 400 Gb/s, supporting InfiniBand and Ethernet. Final topology depends on the deployment.
Is DGX Vera Rubin NVL72 liquid cooled?
Yes. NVIDIA describes Vera Rubin NVL72 as a liquid-cooled rack-scale platform. Facility cooling requirements should be validated before procurement.
How does Vera Rubin compare with GB300 NVL72?
Both are 72-GPU rack-scale systems, but Vera Rubin moves to Rubin GPUs, Vera CPUs, sixth-generation NVLink, ConnectX-9 and BlueField-4. NVIDIA’s September 2026 MLPerf preview reported higher throughput for Vera Rubin in selected Qwen3-VL and DeepSeek-R1 comparisons. Deployment timing, facility readiness and real workload economics should be considered alongside benchmark results.
What is the price of NVIDIA DGX Vera Rubin NVL72?
Pricing should be requested for the exact project because the commercial scope can include the system configuration, support, networking, deployment services, logistics and destination requirements. Contact AI Robot Supplier for a written B2B quotation.
Does NVIDIA include enterprise software and support?
NVIDIA’s current DGX product specification lists NVIDIA Mission Control, NVIDIA AI Enterprise and NVIDIA DGX OS, plus three years of enterprise business-standard hardware and software support. Confirm the entitlement and regional service terms in the final quotation.
Compare NVIDIA AI infrastructure
Request a NVIDIA DGX Vera Rubin NVL72 quotation
For an accurate B2B offer, include quantity, destination country, required deployment date, target workloads and any known networking or data-center requirements. Final availability, configuration and commercial terms will be confirmed in writing.
Editorial / specification note: NVIDIA marks current DGX Vera Rubin NVL72 specifications as preliminary and subject to change. Manufacturer performance figures and MLPerf comparisons are presented with their stated benchmark context. Final configuration, compatibility, support, deployment scope and commercial terms should be verified before purchase.