NVIDIA HGX B300 8-GPU Blackwell Ultra Node
$450,400.00
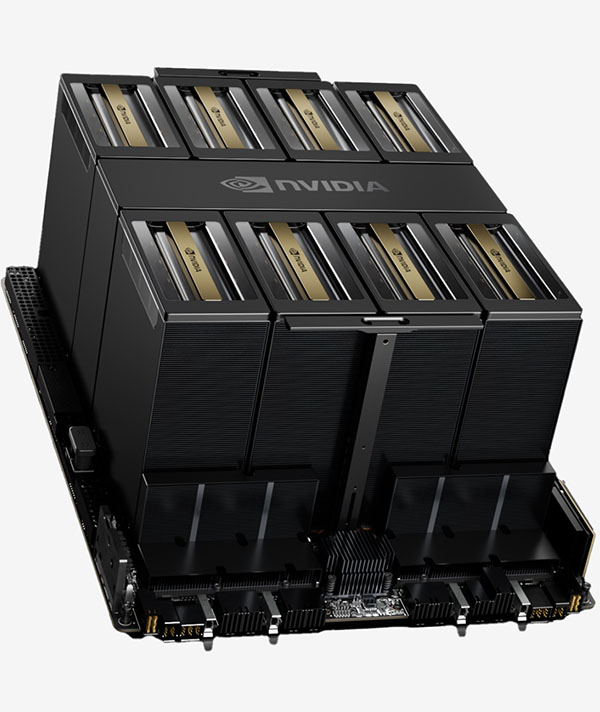
NVIDIA HGX B300 8-GPU Blackwell Ultra Node — 8 × Blackwell Ultra GPUs; 2.1TB total fast GPU memory class. Enterprise 8-GPU HGX node / enterprise AI server platform for large-scale AI training, reasoning inference, model serving, HPC and high-density AI factory infrastructure. Contact us to confirm current configuration and lead time.
Explore Related
Related products, categories and research.
NVIDIA HGX B300 8-GPU Blackwell Ultra Node Overview
NVIDIA HGX B300 8-GPU Blackwell Ultra Node is a 8-GPU HGX node / enterprise AI server platform built for large-scale AI training, reasoning inference, model serving, HPC and high-density AI factory infrastructure. Based on Blackwell Ultra, the configured platform provides 8 × Blackwell Ultra GPUs; 2.1TB total fast GPU memory class and is intended for organizations deploying serious AI infrastructure rather than a conventional single desktop GPU.
This listing deliberately describes the complete commercial assembly or workstation configuration used for pricing. It should not be interpreted as the price of one loose accelerator. That distinction is important for procurement, Google product accuracy and compatibility planning.
Organizations evaluating the NVIDIA HGX B300 8-GPU Blackwell Ultra Node should review workload requirements, power and cooling, host-platform validation, networking, software stack, rack or workstation requirements, quantity, support route and lead time. AI Robot Supplier can confirm the required configuration before a formal quotation or proforma invoice is issued.
Key Features
- Enterprise AI platform: designed for large-scale AI training, reasoning inference, model serving, HPC and high-density AI factory infrastructure.
- High-capacity accelerator memory: 8 × Blackwell Ultra GPUs; 2.1TB total fast GPU memory class.
- Modern accelerator architecture: Blackwell Ultra.
- System-level deployment: this product is sold as the named multi-accelerator assembly or workstation configuration, not as a generic loose GPU.
- Pre-order validation: exact part numbers, included hardware, warranty route, shipping and lead time can be confirmed before payment.
System-level AI performance depends on more than accelerator specifications. CPU architecture, host memory, storage throughput, interconnect topology, Ethernet or InfiniBand fabric, chassis thermal design and framework support can materially change workload throughput. Buyers planning production AI infrastructure should validate the complete system against the intended model sizes and concurrency targets.
NVIDIA HGX B300 8-GPU Blackwell Ultra Node Applications
The NVIDIA HGX B300 8-GPU Blackwell Ultra Node is designed for large-scale AI training, reasoning inference, model serving, HPC and high-density AI factory infrastructure. Typical deployments include private AI infrastructure, enterprise model serving, research clusters, scientific workloads and advanced generative AI development where large accelerator-memory capacity and high-bandwidth compute are important.
AI Training and Inference
Multi-accelerator systems can support large models and higher concurrency than a typical workstation GPU, but actual results depend on precision, framework versions, batch size, model architecture, networking and software optimization. Confirm support for your intended framework and model before procurement.
HPC and Research
For HPC and scientific workloads, verify application support for the relevant accelerator ecosystem and ensure the system’s CPU, storage, networking and cooling design match the workload profile.
Enterprise Deployment
Production deployments should include capacity planning for power, rack space or workstation installation, network fabric, redundancy, support and future scaling. For quantity orders, provide the intended deployment environment when requesting a quotation.
NVIDIA HGX B300 8-GPU Blackwell Ultra Node Specifications
| Brand | NVIDIA |
|---|---|
| Architecture | Blackwell Ultra |
| Memory | 8 × Blackwell Ultra GPUs; 2.1TB total fast GPU memory class |
| Product class | 8-GPU HGX node / enterprise AI server platform |
| GPU Configuration | 8 × NVIDIA Blackwell Ultra GPUs |
| Total Fast Memory | 2.1 TB |
| Aggregate Memory Bandwidth | up to 62 TB/s |
| FP4 Tensor Performance | up to 144 PFLOPS sparse / 108 PFLOPS dense |
| FP8/FP6 Tensor Performance | 72 PFLOPS |
| NVLink Switch Bandwidth | 14.4 TB/s |
| Interconnect | 5th-generation NVIDIA NVLink |
| System Type | HGX B300 8-GPU node |
| Availability | Contact AI Robot Supplier to confirm current commercial availability and lead time. |
Configuration note: specifications above describe the referenced commercial system or baseboard configuration. OEM revisions, cooling options, storage, CPU, networking and accessories can vary. Final order specifications should be confirmed on the quotation or proforma invoice.
Compatibility and Deployment
This is enterprise infrastructure and should not be treated as a plug-and-play consumer graphics card. Confirm chassis or rack requirements, accelerator baseboard support, power distribution, cooling, firmware, operating-system support, drivers, management software and network architecture before ordering.
For multi-accelerator systems, also review scale-up and scale-out interconnects, host NUMA topology, storage throughput and cluster orchestration. If integrating into an existing data center, provide the intended rack, power, cooling and network environment for a compatibility review.
NVIDIA HGX B300 8-GPU Blackwell Ultra Node Price and Ordering
The regular price on this product page is based on a verified current commercial reference for the complete named configuration, discounted for AI Robot Supplier. It is not derived by dividing a multi-GPU system price into an invented single-GPU price.
Because high-end AI infrastructure pricing and inventory can change quickly, customers should request confirmation before payment, especially for multiple units. A formal quotation can specify exact configuration, condition, quantity, warranty, delivery destination and estimated lead time.
Explore related products in Networking & AI Infrastructure.
Manufacturer information: NVIDIA product documentation.
NVIDIA HGX B300 8-GPU Blackwell Ultra Node FAQ
Is this price for one GPU?
No. This page is intentionally priced as the exact multi-accelerator assembly or complete workstation named in the product title.
Can this system be used for large language models?
It is designed for enterprise AI workloads, including supported LLM training or inference. Practical model capacity and throughput depend on framework, precision, memory usage and system configuration.
Can I order multiple systems?
Yes. Quantity orders should be confirmed through a formal quotation because enterprise hardware inventory and lead times can change quickly.
What information is needed before ordering?
Provide the required quantity, destination, target workload and any rack, networking, storage or support requirements so the exact configuration can be confirmed.
Does the listed price include shipping and taxes?
Unless explicitly stated on the final quotation, shipping, taxes, import duties and optional integration services are separate and depend on destination.
Why is configuration confirmation important?
Enterprise AI products can have multiple cooling, baseboard, networking and OEM variants. Confirming the exact configuration reduces compatibility and procurement errors.