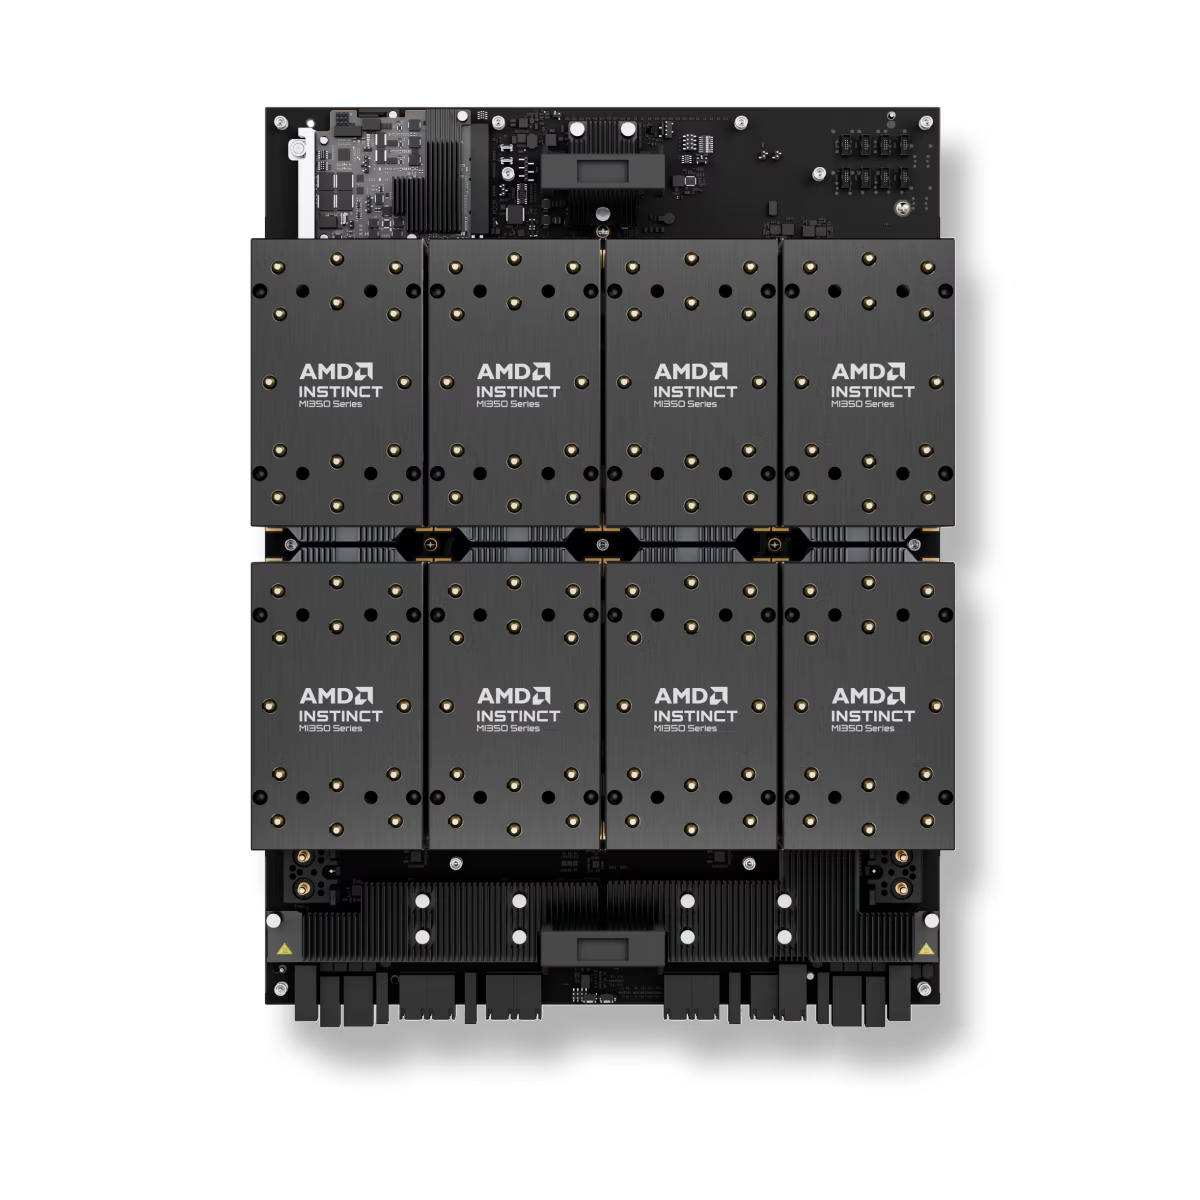
AMD Instinct MI350X 8x OAM UBB8 Assembly 2.3TB HBM3E
$254,947.07
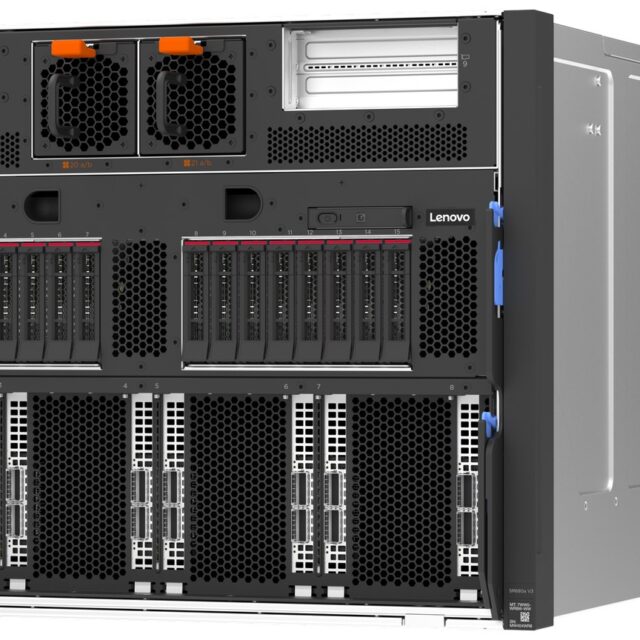
AMD Instinct MI350X eight-GPU UBB8 assembly pairs eight OAM accelerators with 288 GB HBM3E per GPU, totaling 2,304 GB (approximately 2.3 TB) across the platform. Infinity Fabric connects the accelerators directly.
This listing identifies an accelerator assembly. A host server, CPUs, system RAM, storage, network adapters, power supplies and cooling hardware are included only if specified in the supplied bill of materials.
Explore Related
Related products, categories and research.
AMD Instinct MI350X UBB8 is an eight-accelerator assembly for AI training, inference and supported scientific workloads. Eight OAM modules sit on a UBB 2.0 baseboard, with 288 GB HBM3E per GPU and approximately 2.3 TB of aggregate accelerator memory. This listing identifies that assembly; it does not establish a complete server configuration.
AMD Instinct MI350X assembly scope
The distinction between a baseboard assembly and a server matters at installation. The GPUs require a validated host platform with suitable power delivery, cooling, firmware and host connections. CPUs, system RAM, boot storage, network adapters, chassis and power supplies cannot be inferred from the eight-GPU product name. Obtain a part-number-level bill of materials before specifying the surrounding rack or cluster.
The MI350X uses AMD CDNA 4 architecture. It is a different product from the MI355X and from the MI350P PCIe card. A PCIe 5.0 host interface does not make an OAM module a conventional add-in card for a workstation slot. Match the module and baseboard to the host manufacturer’s supported configuration.
UBB8 reference specifications
| Accelerators | 8 × AMD Instinct MI350X OAM |
|---|---|
| Baseboard | UBB 2.0, eight-accelerator platform |
| Architecture | AMD CDNA 4 |
| HBM3E capacity | 288 GB per GPU; 2,304 GB aggregate, commonly rounded to 2.3 TB |
| Memory bandwidth | Up to 8 TB/s per GPU, peak theoretical |
| Compute resources | 256 compute units and 16,384 stream processors per GPU |
| Host connection | PCIe 5.0 x16 per accelerator through the supported platform |
| GPU interconnect | Seven scale-up Infinity Fabric links per GPU, fully connecting the eight GPUs |
| Module power | 1,000 W board-power specification per GPU; not total server input power |
| Cooling reference | Passive OAM; host-system thermal design required |
These values describe AMD’s platform reference capabilities, not a record of tests performed on this offered assembly. The supplied part numbers, firmware revision, operating limits and condition still require confirmation.
HBM3E capacity and workload planning
The aggregate memory figure is the sum across eight accelerators. It should not be interpreted as one GPU with a single 2.3 TB local memory allocation. Plan model placement around the memory available to each GPU and the framework’s distributed execution method.
For inference, include model weights, runtime workspace and key-value cache in the capacity estimate. Context length, request concurrency and precision change that estimate. For training, add gradients, optimizer state and activations. A model’s parameter count alone cannot establish whether the full run will fit or achieve the throughput required.
Memory bandwidth is a peak hardware figure. Application behavior depends on access patterns, kernel efficiency and communication between devices. Compare the intended workload on the selected software stack rather than treating the bandwidth number as a measured application result.
Direct Infinity Fabric connections
AMD’s platform brochure describes direct, fully meshed GPU-to-GPU connectivity, with seven 153.6 GB/s bidirectional links per GPU. These scale-up connections serve communication within the eight-GPU assembly. They are distinct from the network fabric used to communicate between servers.
A multi-node deployment therefore needs a separate network design. Specify network adapters, switch topology, cables and congestion controls alongside the host server. The presence of Infinity Fabric on the baseboard does not establish that an external Ethernet or InfiniBand adapter is supplied.
Power and cooling integration
Eight modules at the 1,000 W reference board-power figure represent an 8 kW accelerator budget before adding CPUs, memory, storage, fans and power-conversion losses. Size the server and rack from the manufacturer’s complete configuration limits. This arithmetic is a planning subtotal, not a measured wall-power claim.
Passive OAM cooling depends on the surrounding server’s engineered thermal path. Confirm the approved heatsinks or other cooling hardware, airflow requirements and operating environment for the exact assembly. A baseboard form factor shared with another platform generation is insufficient evidence that an existing chassis can safely accept it.
ROCm software and acceptance checks
AMD’s acceptance guide directs users to current ROCm documentation for supported operating systems and dependencies. Record the OS, kernel, ROCm release, framework build and application version together. This makes a compatibility assessment reproducible and avoids treating support for a GPU architecture as support for every software combination.
For an installed system, an agreed acceptance procedure can check that all eight GPUs enumerate, that reported memory and topology match the configuration, and that workload tests complete without errors. Define the test conditions and evidence required before purchase. No acceptance results, benchmark figures or calibration claims are provided by this listing.
Questions before ordering
Is this one loose GPU?
No. The product name identifies eight MI350X OAM accelerators on a UBB8 assembly. Confirm the exact assembly part number and which supporting components are included.
Is 2.3 TB additional CPU memory?
No. It describes aggregate HBM3E attached to the GPUs. Host system RAM is separate and must be specified in the server configuration.
Are software, installation and warranty included?
Those terms are not established by the hardware model. The quotation should separately define software entitlements, integration work, condition, warranty and delivery scope.
Manufacturer resources
Use the AMD MI350X GPU specifications, MI350X platform brochure and AMD acceptance guide to define the configuration and checks. Browse related Networking & AI Infrastructure products for the surrounding deployment.
Related products
Recently viewed
Add AI Robot Supplier as a preferred source on Google.